

Kimi K2 Thinking marks a pivotal inflection point in AI’s evolution. It’s the first open-source model to reach and surpass the performance frontier of proprietary systems like GPT-5 and Claude Sonnet 4.5 in reasoning and agentic capabilities. At just $4.6 million for training (non-official numbers), it achieved that performance at just a fraction of their cost. Open source is catching up fast, and so is China, but at very different economics. If this pace holds, next year’s leaderboard will look very different.
After months of relentless developments in artificial intelligence, the industry finds itself confronting the same existential question at year’s end as it faced at the start of 2025:
Is it getting the fundamental economics all wrong?
Following ChatGPT’s November 2022 launch, conventional wisdom about massive compute and infrastructure costs went largely unquestioned until January 2025, when a Chinese entrepreneur dropped DeepSeek-R1 like a neutron bomb. This open-source LLM seemed to match many of ChatGPT’s performance benchmarks at a fraction of the training cost.
The impact lingers. In August, Andreessen Horowitz’s Martin Casado told The Economist that most startups pitching the firm use Chinese AI models: “I’d say 80% chance [they are] using a Chinese open-source model.” Last week’s GPT-5.1 release faced intense scrutiny, highlighting the pressure on companies spending gargantuan sums on compute.
Now comes another stark AI economic contrast from China.
Last week, AI headlines focused on reports that Thinking Machines Lab, the startup led by former OpenAI CTO Mira Murati, was seeking to raise funding at $50-60 billion valuation, up from $12 billion this summer. The company’s sole product is a private beta tool called “Tinker” for fine-tuning open-source models.
Meanwhile, receiving far less fanfare, earlier this month, Moonshot AI released Kimi K2 Thinking. This open-source model achieved state-of-the-art performance on Humanity’s Last Exam (44.9%), surpassing both GPT-5 (41.7%) and Claude Sonnet 4.5, at just $4.6 million in training costs for its trillion-parameter architecture.
For context: that’s roughly the cost of training a single large language model in 2023, now producing a reasoning system that outperforms the most sophisticated proprietary models on critical benchmarks.
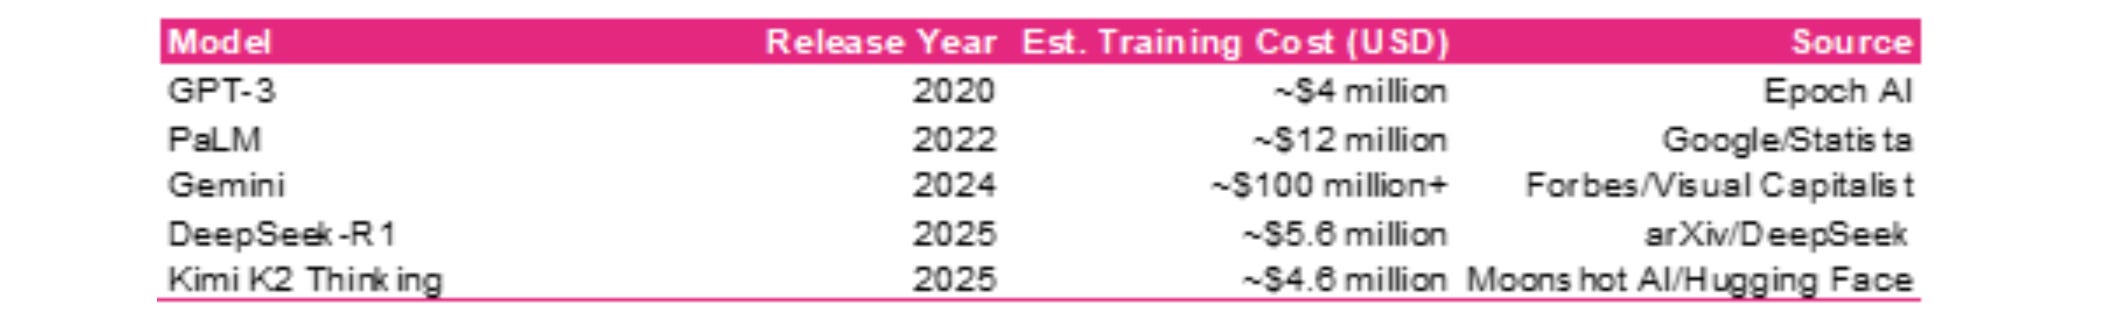
Figure 1. Estimated training costs of SOTA models
And that is only a fraction of the training compute costs.

Figure 2. Training compute (FLOP) for OpenAI models. GPT-6 will likely be trained on more compute than GPT-4.5 per EpochAI. Note GPT-5 used less training compute than GPT-4.5 because OpenAI focused on scaling post-training.
This represents more than another data point in AI’s rapid progress. Kimi K2 Thinking challenges many assumptions about sustainable competitive advantage in AI development. Moonshot demonstrates that architectural innovations enabling advanced reasoning can be achieved through algorithmic efficiency rather than pure capital deployment - via test-time compute scaling, chain-of-thought integration, and adaptive tool orchestration.
This marks an inflection point. Open source has caught up to the closed frontier, not just in raw capabilities, but in the sophisticated reasoning and agentic behavior that defines second-wave AI systems. These capabilities are required to build autonomous agents that can reliably complete complex, multi-step tasks in production environments. By democratizing access to the emerging automation these systems enable, these open-source models allow even more companies to access the exponential potential of Orchestration Economics that I’ve written about previously.
In other words, another neutron bomb. Except unlike DeepSeek, its detonation failed to shake markets or rattle executive nerves or prompt a philosophical reckoning. It has largely gone unnoticed.
But it shouldn’t be ignored.
Interleaved Thinking: Inside Kimi K2’s Core Innovation
Let’s start by understanding Kimi K2 Thinking’s most significant innovation - one that reimagines the relationship between reasoning and action.
The trillion-parameter scale with 32 billion active parameters via Mixture-of-Experts (MoE) architecture is impressive (MoE is a machine learning architecture that enhances model efficiency and performance by dividing a neural network into multiple specialized sub-networks, called “experts,” each handling a subset of the input data or specific tasks). But what truly matters is the architectural paradigm shift in how the model integrates reasoning with tool use.
Previous reasoning models, including OpenAI’s o1 series, treated tool use as separate from reasoning. The model generates a chain of thought, produces an answer, and only then might invoke external tools. This sequential approach creates a rigid boundary between thinking and acting that limits the model’s ability to refine reasoning based on new information gathered through tool use.
Kimi K2 Thinking employs what Moonshot calls “interleaved thinking and tool use.” This is a paradigm where reasoning tokens and function calls alternate fluidly within the same inference pass. The model thinks, acts, observes results, thinks again, acts differently based on new information, and continues this dynamic cycle for hundreds of steps without degradation.
This enables genuinely agentic behavior. As Simon Willison defines it: “An LLM agent runs tools in a loop to achieve a goal.” K2 Thinking embodies this definition at scale. It pursues goals adaptively across 200-300 sequential tool calls while maintaining coherent goal pursuit, adjusting strategy based on environmental feedback rather than executing rigid plans.
This capability is confirmed by BrowseComp, a benchmark testing models’ ability to browse, search, and reason over hard-to-find real-world web information. K2 Thinking achieved 60.2%, more than double the human baseline of 29.2% and substantially ahead of GPT-5’s performance.
More specifically, the technical implementation relies on three key innovations:
End-to-end agent training: Rather than bolting reasoning capabilities onto a pretrained model, Moonshot employs a unified training methodology that teaches the model when and how to invoke tools during reasoning itself. The model learns to generate diverse tool-calling trajectories following the “Reason + Act” paradigm, where each action informs subsequent reasoning steps.
Native INT4 quantization: Kimi K2 supports INT4 inference with minimal performance degradation through Quantization-Aware Training applied during post-training. This achieves roughly 2x speed improvements in low-latency mode. Such an advance is critical for enabling the hundreds of sequential inference steps that advanced reasoning requires while maintaining economic viability.
256k context window: The extended context enables the model to maintain state across long reasoning chains involving multiple tool calls and intermediate results. This is similar to how OpenAI’s GPT-5 (up to 400K tokens) and Anthropic’s Claude Sonnet 4.5 (200K-1M tokens) are positioned for handling massive, multi-step agentic workflows. When tool execution results exceed the context limit, K2 employs dynamic context management that selectively preserves relevant information while hiding previous outputs, ensuring coherence without the need for even larger raw scales.
These breakthroughs directly enable the interleaved thinking paradigm to shine in real-world applications. For executives evaluating AI investments, this translates to tangible ROI:
End-to-end training ensures agents adapt strategies mid-task without derailing.
Efficient quantization keeps inference costs low for scalable deployments.
The massive context window prevents information loss in extended workflows, allowing AI systems to handle complex, error-prone tasks autonomously, learning from mistakes in real-time rather than requiring constant human fixes.
But K2’s achievement carries far greater significance than these implementation details alone: It’s the first open-source model to truly compete at the frontier of reasoning capabilities, fundamentally altering the competitive dynamics between open and closed AI systems.